





Mean Time to Acknowledge (MTTA)
Last updated on October 16, 2026
What is mean time to acknowledge (MTTA)?
Mean Time to Acknowledge (MTTA) is the average time between when an alert fires and when a human or automated system claims ownership of it, measured in minutes. Also referred to as acknowledgment time or ack time, MTTA is a leading indicator of incident response health. Teams with low MTTA tend to carry that discipline forward into faster diagnosis and resolution.
Why MTTA matters in incident management
MTTA is the critical handoff point in the incident lifecycle: prevent, detect, triage, resolve. Everything that follows acknowledgment, including diagnosis, mitigation, and resolution, depends on that first ownership claim. You can’t triage an incident no one has accepted.
Acknowledgment is where the incident lifecycle actually starts, and compressing it’s the first lever any incident response KPI review should examine.
How to calculate MTTA
MTTA formula:
MTTA = Sum of (First Acknowledgment Time − Alert or Incident Creation Time) / Total Number of Incidents
Unit: minutes
In most platforms, MTTA is calculated as the elapsed time between the incident’s creation timestamp (the point at which the alert fires and an incident is created) and the first assign or acknowledge action taken by an operator. That distinction matters: the clock starts when the alert fires, not when a responder notices it sitting in a queue.
The MTTA calculation stops at acknowledgment. MTTR keeps going through diagnosis, remediation, and resolution. These are related but separate clocks.
Worked calculation example
Suppose three separate P1 incidents are acknowledged 8, 14, and 5 minutes after their alerts fire.
MTTA = (8 + 14 + 5) / 3 = 9 minutes
A 9-minute MTTA is workable for some environments. High-maturity NOCs processing critical P1 incidents commonly target under 5 minutes. What matters most is whether your MTTA is trending down over time.
MTTA vs. MTTR, MTTD, MTBF, and MTTF
| Metric | Full Name | What It Measures | Relationship to MTTA |
|---|---|---|---|
| MTTA | Mean Time to Acknowledge | Time from alert to ownership | The baseline: starts the response clock |
| MTTR | Mean Time to Repair/Resolve | Time from incident start to full resolution | MTTA is a direct input; high MTTA inflates MTTR |
| MTTD | Mean Time to Detect | Time from incident start to alert firing | Precedes MTTA; together they form the pre-response window |
| MTBF | Mean Time Between Failures | Average uptime between incidents | Broader reliability metric; not directly about response speed |
| MTTF | Mean Time to Failure | Expected lifespan before first failure | Reliability and hardware planning; not an incident response KPI |
MTTD and MTTA together form the complete pre-response window. Compressing MTTD shortens time to detection. Compressing MTTA shortens time to action. Do both, and MTTR drops directly.
What causes high MTTA
High MTTA is rarely a people problem. It’s an alert noise problem. When engineers face thousands of raw, undeduplicated alerts, identifying the right one to acknowledge is genuinely hard.
- Alert noise and volume. Low-fidelity alerts flood the queue and bury the critical ones. Engineers spend time scanning rather than acting.
- Poor alert routing. The right alert reaching the wrong team, or no team at all, means incidents sit unacknowledged until someone notices them.
- Alert fatigue. After enough false positives, acknowledgment rates drop. This is a system design problem, not a motivation problem.
Bungie achieved 99% alert compression using the BigPanda platform. Cambia Health Solutions now identifies critical alerts at L0/L1 in 30 seconds. Both results start with reducing the volume that reaches responders.
How to reduce MTTA
- Consolidate alert streams into a single view. Context switching between tools adds seconds that compound across every incident.
- Deduplicate and correlate before routing. A storage failure that generates 400 individual alerts should reach a responder as one incident.
- Enrich incidents with context before they land. A responder who already knows what broke can acknowledge with confidence rather than beginning triage from zero.
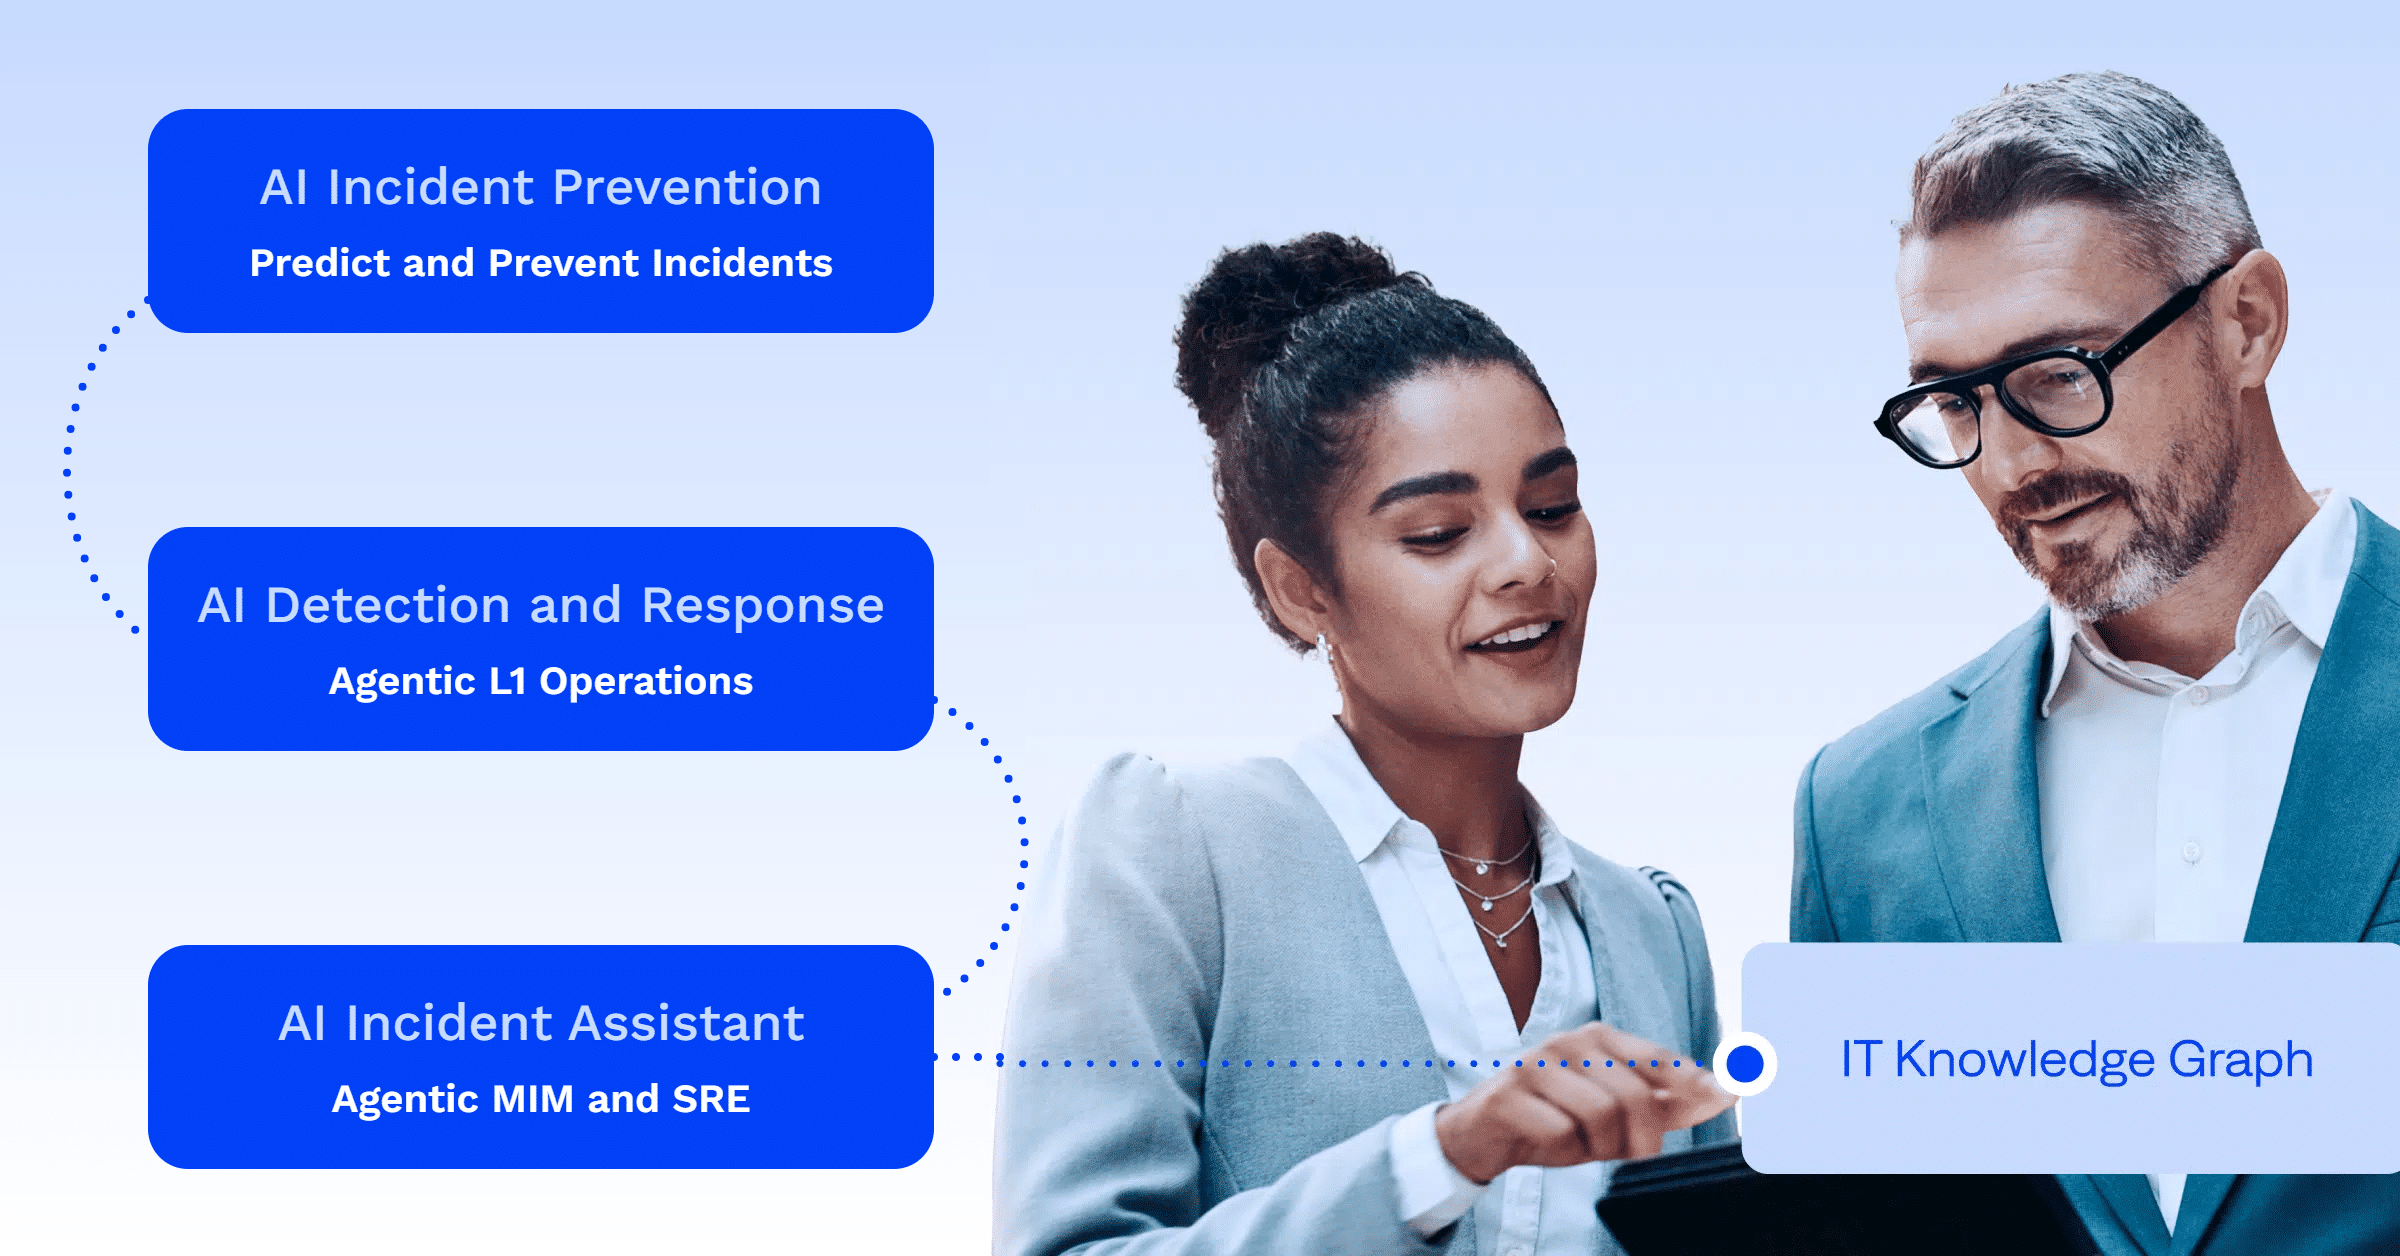
For how automated correlation and enrichment reduce acknowledgment time at the system level, see AI Detection and Response.
How Agentic ITOps compresses MTTA
For routine, high-frequency incident types, the L1 Agent handles acknowledgment and triage autonomously, driving MTTA toward zero before a human queue is involved. The IT Knowledge Graph helps incidents reach human responders with root cause candidates and topology context. The California DMV cut incident response from four to eight hours to under 15 minutes using the BigPanda platform.
MTTA in practice
For P1 and P0 incidents, MTTA translates directly to revenue exposure. Unplanned downtime costs large enterprises an average of $23,750 per minute, according to EMA research. A 12-minute MTTA on a P1 represents roughly $285,000 in potential exposure before anyone has started working the problem. For how MTTA interacts with on-call schedules and escalation thresholds, see On-Call Management and Escalation Management.
Frequently asked questions about mean time to acknowledge (MTTA)
What is a good MTTA benchmark?
It depends on incident severity and industry. For P1 incidents, high-maturity NOCs commonly target under 5 minutes. Raw benchmarks matter less than whether your MTTA is trending down within your own environment. A team that moves from 18 minutes to 7 minutes over two quarters has made real progress regardless of what a published benchmark says.
What is the difference between MTTA and MTTR?
MTTA measures time to acknowledge, meaning the moment ownership is claimed. MTTR measures time to resolve, meaning the moment the incident is closed. MTTA is an input to MTTR. You can’t resolve what no one has claimed, so a high MTTA inflates MTTR directly.
How does alert noise affect MTTA?
Directly and severely. When alert volume is high and low-fidelity, engineers can’t quickly identify which alert to acknowledge. MTTA climbs across every incident type, not just the noisy ones, because responder attention is spread thin.
Can MTTA be automated?
Yes. With Agentic ITOps, automated L1 agents acknowledge and triage known incident types at machine speed. For routine, high-frequency events, this drives MTTA toward zero. Human acknowledgment stays where it belongs: on the incidents that genuinely need human judgment.
Check out more related content
PLATFORM
Alert aggregation and incident management
Handle incidents faster and eliminate alert fatigue with BigPanda’s intelligent alert correlation and unified incident response.