





The four decisions every IT leader must make before deploying Agentic IT Operations

If you ask most enterprise ITOps leaders how their agentic AI initiatives are going, and they’ll point to which agents they’ve deployed, which vendors they’ve picked, or which specific workflows they’ve automated.
It’s the wrong first question to ask when starting the conversation about successfully deploying AI in ITOps, and here’s the data that shows why.
A recent Harris Poll survey of more than 300 U.S. data and AI decision-makers found that while 90% of organizations are actively deploying autonomous AI agents, 76% have hit critical roadblocks moving those agents from pilot into full production. Other analysts are seeing the same pattern emerge, as Gartner® predicts that by 2029, 70% of enterprises will deploy agentic AI to operate their IT infrastructure, up from under 5% in 2025. At the same time, the firm also expects more than 40% of agentic AI projects to be canceled by the end of 2027.
In short, while nearly everyone is deploying AI in their ITOps, settling the debate over whether they need to adopt the technology, most are stalling in their attempts to deploy it successfully. And it isn’t the technology itself that separates the programs that scale from the ones that quietly fail.
The deciding factors are choices unrelated to model selection. Before an AI agent ever touches a production incident, leadership has to decide where it’s allowed to reason, when it’s allowed to act, how its performance will be judged, and who answers for the results.
At BigPanda, we’ve distilled those choices into four decisions: scope, autonomy, metrics, and the change agent. We recently broke down the roadblocks the Harris Poll research surfaced and why a living data foundation is the way past them. In this article, we’ll look at the same challenge from the leadership side and explore the four decisions that IT leaders must make to turn a promising pilot into a functional operating model. We explored why major incident management is the right proving ground in a previous post from this series, so now let’s cover what you need to decide before the pilot begins.
Decision 1 – Scope: Where do you let AI reason?
When it comes to scoping AI into ITOps processes, the instinct is likely to sort by risk. It’s understandable to want to keep AI away from anything important, while letting it loose on trivial tasks. This might seem like automating low-hanging fruit while mitigating risk, but it’s also how programs end up automating work nobody cares about while the expensive problems stay untouched.
A better approach starts with a series of different questions. Across your most critical operational processes, which specific activities should AI own outright, which should it support, and which should it simply watch?
A major incident, for example, isn’t a single unit of work. Major incidents span distinct stages, from pulling together context and assembling responders through investigation, stakeholder communication, and documentation. Each stage carries its own risk profile, and several of them are safe for AI to handle even when the incident itself is severe. Summarizing what changed before a Sev1 bridge call convenes is low-risk work that carries enormous value.
To make better scoping decisions, we strongly recommend that scope follows data confidence. In the Harris Poll research, 72% of decision-makers said their AI shortfalls almost always trace back to a poor or unaligned data foundation. That finding should directly shape your scoping decisions by giving AI room to reason wherever your knowledge foundation can support it, such as services with current topology, rich incident history, and change data related to incident response. Where the environment is thinly mapped, assign your AI agents a different job, such as observing, enriching, and building up the record until the evidence supports a bigger role.
A living intelligence layer like the BigPanda IT Knowledge Graph makes this practical, because it learns from every incident and steadily expands the territory where AI can operate with confidence.
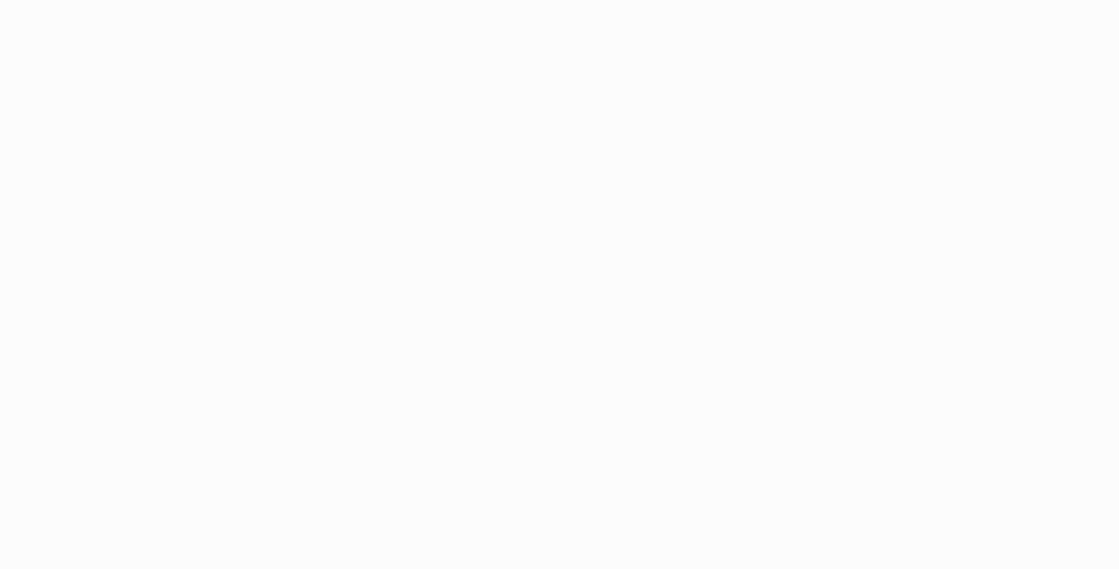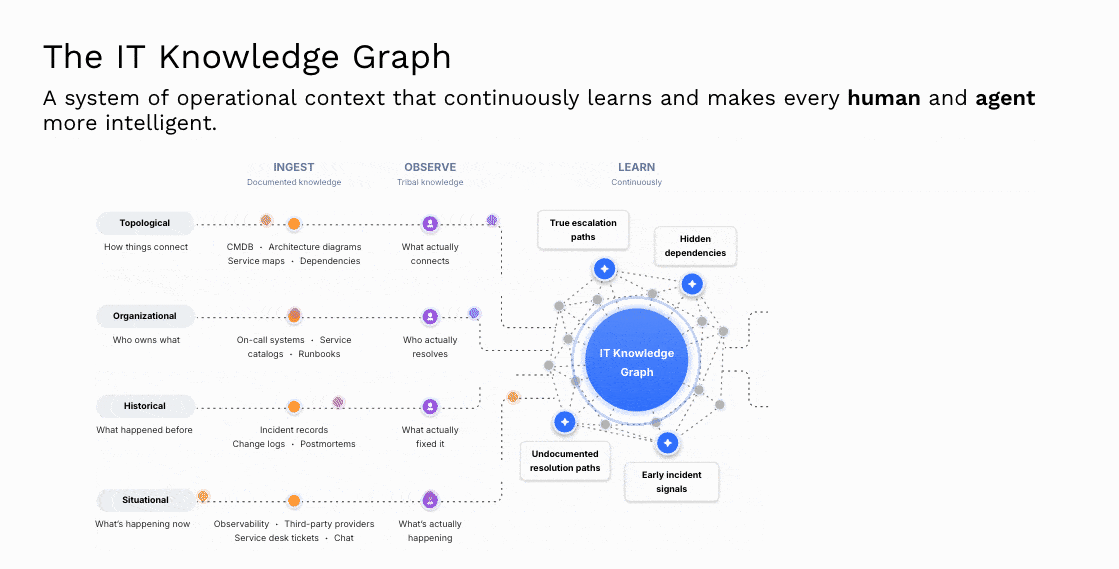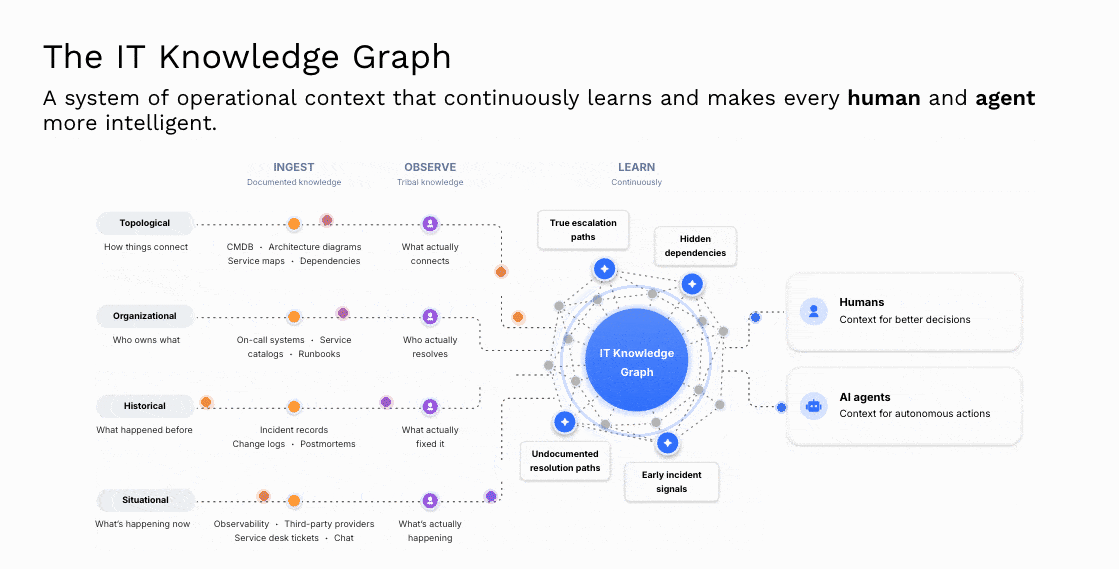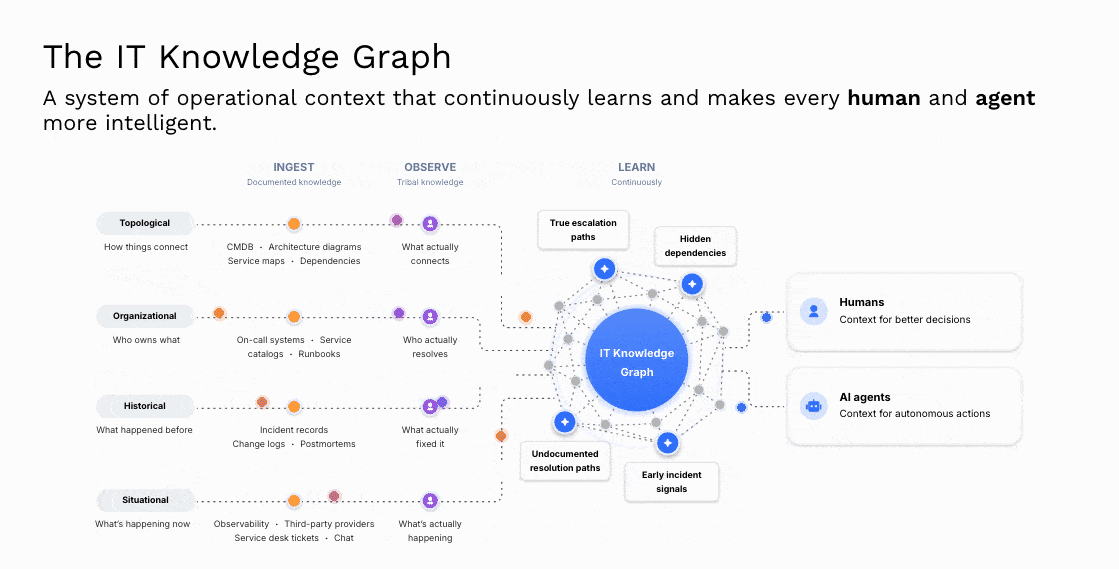
Scoping by data confidence shifts your internal conversations from how much the organization fears AI to what the evidence supports. One is a stalemate, while the other feeds and informs a roadmap.
Decision 2 — Autonomy: How far can AI act without a human in the loop?
Most organizations frame autonomy as a single policy choice to be settled once, such as “do we keep a human in the loop or not?” Framed that way, the cautious answer usually wins, and the program’s ceiling gets set on day one, before your AI agents have the chance to demonstrate what they can safely handle.
The Harris Poll data shows where that caution leads. Just over half (51%) of respondents said their teams spend significant staff hours reviewing and correcting agent outputs before they go live. Early in a deployment, those reviews are necessary and correct. The problem is endless reviews without a clear exit plan. If your senior engineers have to check every agent output forever, you haven’t automated anything; you’ve just added extra steps. That’s called the verification tax, and it’s where many AI pilots quietly die.
You can break this cycle by treating autonomation as a promotion system rather than a policy. Picture a ladder where at the bottom, AI advises, and a human executes. One rung up, AI acts with human approval. Then AI acts on its own while humans review afterward. At the top, AI operates independently within approved categories of work. No capability starts at the top; promotion is earned, not scheduled, and the climb runs on evidence such as suggestion accuracy, approval rates on drafted communications, how often humans override the AI’s calls, and how cleanly your AI executes the actions it takes.
By following the ladder principle, knowledge work is promoted first, such as assembling context, matching incidents to history, and drafting summaries. This is because an imperfect suggestion will have minimal negative impact and gets caught immediately. Coordination and communication climb next, while actions that change production systems climb last. Every serious vendor still routes high-risk production changes through human approval, so if a vendor offers you fully autonomous remediation on critical incidents in month one, it should be treated as a red flag.
One more element belongs in this decision, and it’s the one that wins over skeptical CIOs: the ladder runs both directions. Performance thresholds can automatically walk a capability back down a rung the moment its metrics slip, giving your organization the confidence to extend scope to more important processes.
Decision 3 — Metrics: Which numbers go in your business review?
Agentic AI programs generate a flood of measurable activity, including alerts processed, incidents touched, and agents running. However, the reality is that filling a dashboard with twenty KPIs yields an overwhelming number of measurements to act on, while also signaling that the team hasn’t decided what success means.
We recommend three measurements, which together answer the three questions every business review will ask: does agentic AI make our operations faster, cheaper, and more reliable?

It’s equally important to leave vanity metrics like activity counts, percentages without a baseline, and averages that mix AI-assisted work with everything else out of the review. Metrics like these prove nothing, and erode credibility with the audience you most need to keep.
Decision 4 — The change agent: Who owns the shift from pilot to operating model?
MIT research found that 95% of enterprise generative AI pilots fail to deliver their intended operational impact, and the model is almost never the reason. What’s missing is everything around the model, such as integrations, governance, reliability engineering, and above all, a person whose job depends on the pilot successfully becoming a production operating model.
The Harris Poll research revealed an organizational pattern worth noting: more than half of organizations moved their AI function closer to the data organization over the past year. That’s sensible for governing data risk. But in IT operations, governance isn’t the same as ownership. Somebody has to decide when an agent graduates from shadow mode to the live war room, and somebody has to answer for MTTR when it does. A center of excellence can advise. It can’t own a Sev1.
The change agent needs to be a single person, not a committee. Committees produce recommendations; owners produce outcomes. The right owner is the leader who already runs the process AI is transforming, already holds authority when that process is under pressure, and already answers to leadership for its results. For incident management, that’s your major incident manager or head of IT operations.
So what does this owner actually do? They set the exit criteria for each phase of the rollout and make the go/no-go calls. They run the reviews that promote or demote AI capabilities on the autonomy ladder. They translate your existing escalation and approval protocols into AI workflows the platform can execute, so the technology adapts to your process rather than the reverse. And, critically, they make sure their people are prepared, trained, and supported so this transformation succeeds.
Incident commanders become supervisors of an AI partner rather than human routers. Responders learn to interrogate an assistant in natural language. Veteran engineers hear early and often that the system is capturing their expertise and multiplying it, not harvesting it to replace them.
That last responsibility deserves more attention than it gets, because your senior responders carry the institutional knowledge your entire operation runs on.
Four Decisions, one Agentic ITOps platform
If you read back through these Four Decisions, you’ll notice none of them stands alone. Your data confidence sets the scope. Within that scope, performance earns autonomy, one rung at a time. Your three numbers supply the evidence those promotions run on. And your change agent turns evidence into decisions, week after week, until the pilot has become the way your organization operates.
That’s the real answer to “which agent do we deploy?” It was never a procurement question. It’s an operating model with four moving parts — and leadership holds every one of them. The 76% of organizations stuck between pilot and production aren’t stuck because they chose the wrong agent. They’re stuck because nobody made these four decisions on purpose.
These decisions are critical for ensuring your Agentic ITOps deployment is successful. We’ve put all of these key learnings, and many more, into The Four Decisions: A 90-Day Leadership Playbook for Agentic ITOps. Inside, you’ll find a breakdown of where AI should reason first in the incident lifecycle, an autonomy ladder with promotion criteria and automatic circuit breakers, the key metrics that belong in your business review, and a phase-by-phase 90-day plan with clear exit criteria.
Key takeaways from this blog:
- Scope follows data confidence, not fear. With 72% of decision-makers tracing AI shortfalls to a poor data foundation, the scope decision should be evidence-based: let AI reason where topology is validated and incident history runs deep; everywhere else, it observes and enriches until the data supports a bigger role.
- Autonomy is a promotion system, not a policy. Capabilities climb a ladder — advise, act with approval, act with review, act independently — on measured performance, with knowledge work promoted first and production-changing actions last. The ladder runs both directions, and that’s what makes it safe to climb.
- Three numbers beat twenty. A speed number (MTTR vs. baseline, AI-assisted incidents reported separately), a cost number (bridge-call hours per major incident), and a trust number (the human override rate) answer the only questions a business review will ask: faster, cheaper, trustworthy.
- Name one owner, not a committee. MIT found 95% of enterprise GenAI pilots fail to deliver their intended operational impact — and the gap is organizational. The leader who already runs the process, holds authority under pressure, and answers for results is the one who turns a pilot into an operating model.
- The four decisions operate as a single system. Data confidence sets scope, performance earns autonomy within it, the three numbers supply the evidence, and the change agent converts that evidence into decisions. The 76% of programs stuck in pilot are stuck because nobody made these decisions deliberately.