





What is auto-remediation?
Auto-remediation is the detection and resolution of IT incidents without human intervention. The system detects a fault condition (a crashed service, degraded performance, an alert threshold breach) and applies a corrective action on its own: restarting a process, scaling a resource, rerouting traffic, or suppressing a noise alert. In IT operations, auto-remediation exists to restore service availability and keep infrastructure running. This is distinct from cybersecurity remediation, which typically means isolating endpoints or deploying patches in response to threats. Also referred to as automated remediation, automatic remediation, and autonomous remediation.
The problem auto-remediation solves
L1 analysts get paged at 2 a.m. for false positives, and end users still report 65% of incidents because monitoring tools miss them first. Enterprise Management Associates puts unplanned downtime at an average of $23,750 per minute for large enterprises. Auto-remediation closes the gap between detection and action, resolving qualifying incidents before a human ever needs to.
How auto-remediation works: a six-step workflow
- Detection: Monitoring tools identify an anomaly or threshold breach across infrastructure, applications, or network layers.
- Correlation and enrichment: Related alerts are grouped into a single incident with added context: affected service, owner, dependencies, and recent change history.
- Root cause identification: Using historical data and topology, the system determines the most likely cause, not just the symptom.
- Remediation action selection: A pre-defined runbook or AI-reasoned action is matched to the incident type based on what has worked before.
- Execution: The corrective action runs automatically: a service restart, a config rollback, a resource scaling event, or an automatic ticket closure.
- Validation and escalation: The system confirms whether the fix worked. If it doesn’t, the incident escalates immediately with full context attached, so the responding engineer doesn’t start from zero.
Step 2 is where most implementations succeed or fail. Without good correlation and enrichment, downstream steps act on incomplete information. See AIOps for how the detection-to-correlation layer works, and automated incident response and management for how that feeds a broader response workflow.
Rules-based vs. AI-driven remediation
Rules-based remediation uses if-then logic. It’s reliable for simple scenarios but brittle when conditions change faster than rules get updated. AI-driven remediation reasons across historical outcomes, topology data, and real-time signals to select the best action, even for incidents that don’t match a known pattern. The L1 Agent applies that reasoning at L1 volume, acting within defined safety guardrails before any human needs to engage.
Auto-remediation vs. runbook automation: what is the difference?
Runbook automation executes a documented procedure in response to a trigger. Auto-remediation is broader: it includes detection, correlation, decision-making, and execution. The difference is the decision layer. An organization can have runbook automation without auto-remediation if humans still decide when to run the runbook.
Manual remediation vs. auto-remediation
| Dimension | Manual Remediation | Auto-Remediation |
|---|---|---|
| Off-hours coverage | Depends on on-call availability | Continuous |
| Speed | Minutes to hours | Seconds to minutes |
| Scalability | Limited by available staff | Scales with alert volume |
| Consistency | Varies by analyst and shift | Same validated action every time |
| Context at execution | Depends on individual knowledge | Enriched from topology and history |
| Escalation quality | Varies by responder | Full incident context every time |
| Cost per incident | Higher due to L1 analyst involvement | Lower by resolving before human intervention |
| Risk of human error | Present throughout | Reduced through validated guardrails |
The gap widens at scale. A single analyst handling 200 alerts per shift makes different decisions than the same analyst handling 20. Auto-remediation takes shift and workload out of the equation.
Benefits of automated remediation for ITOps teams
- Faster MTTR: Incidents resolve in seconds or minutes, without waiting for an analyst to triage, acknowledge, and act.
- Reduced alert fatigue: Correlation suppresses noise and false positives before they reach the queue, so the alerts that surface are the ones that need attention.
- Consistent execution: The same validated action runs every time, regardless of shift, workload, or individual familiarity with the affected service.
- Reclaimed engineer time: Automating L1 detection and response handles high-volume incident types without a human in the loop, so engineers spend their time on L2/L3 problems instead of repetitive triage.
- Lower incident cost: Fewer engineer-hours per incident and shorter downtime windows reduce both direct labor costs and indirect costs from service degradation. A major airline saved $11.3 million in annual labor costs by automating L1 workflows, and FreeWheel saves 20 hours per incident with auto-remediation.
Auto-remediation use cases in IT operations
- Service restart: A crashed process is detected and restarted automatically. No ticket opens, no pager fires.
- Alert storm suppression: A single root-cause event triggers thousands of downstream alerts. Correlation groups them into one incident and suppresses the redundant ones.
- Runbook-driven resolution: A known error condition triggers the associated runbook without waiting for a human to recognize the pattern.
- Change-related rollback: When a deployment degrades performance, correlating the incident with the recent change lets teams roll it back quickly, and within defined guardrails that rollback can run automatically.
- Incident auto-close: A transient condition clears on its own and the incident closes without analyst review.
- Context-rich auto-routing: Incidents that can’t be auto-resolved go to the right team immediately with full enrichment attached.
Auto-remediation in AIOps and Agentic ITOps
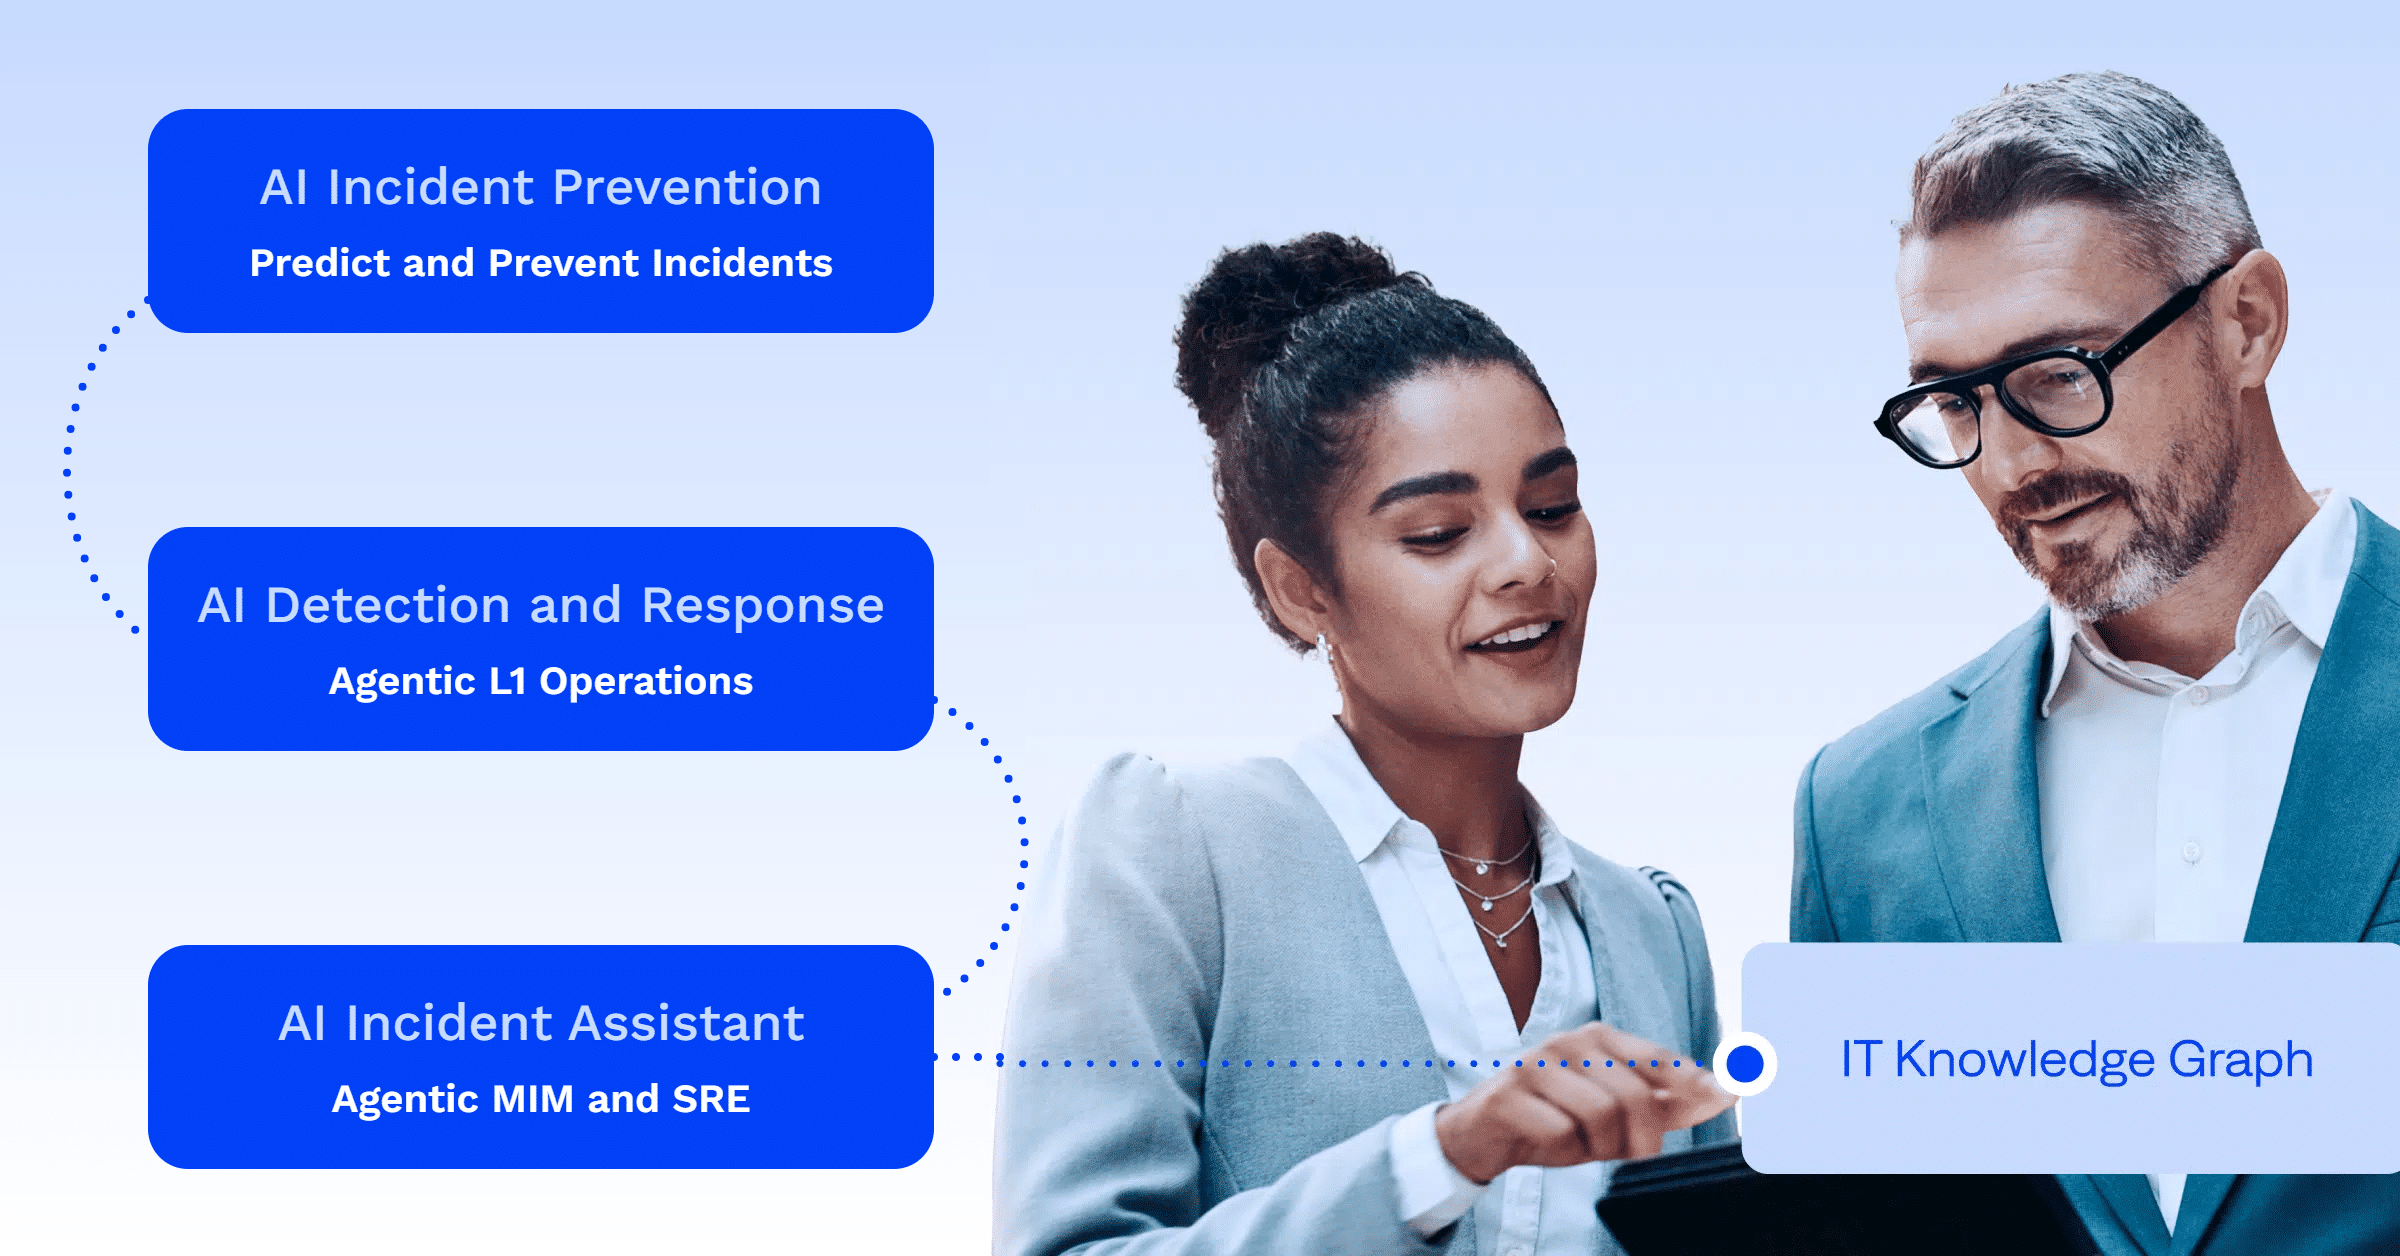
AIOps applies machine learning and AI to IT operations data. Auto-remediation is the action layer that turns those insights into fixes. Agentic ITOps takes that further, with AI agents that reason, act, and learn within defined guardrails to handle incidents end to end. The L1 Agent and automated incident response and management show how those guardrails work in a production environment. For the full detection-to-response loop, see AI Detection and Response.
Common auto-remediation challenges and how to address them
What if the automated fix makes things worse?
Start with low-risk, high-volume incident types and validate outcomes before expanding scope. Safety gates, meaning defined guardrails that block action outside approved parameters, keep the blast radius contained while confidence is being built. Graduated autonomy builds the trust to go further.
Our CMDB and data are too messy for automation to work.
AI reasoning draws on historical incident outcomes and operational context, not just structured inventory records, so the first automations can run with the data you already have.
We don’t have our runbooks documented.
AI surfaces historical incident outcomes and resolution patterns from work your team has already done, which is enough to bootstrap remediation logic before anything gets formally written down.
Alert noise makes it hard to know what to automate.
Correlation and enrichment must come before execution. Fix the signal quality first.
Best practices for implementing auto-remediation
- Start with high-volume, low-risk incident types: Identify the most common L1 ticket categories and automate those first.
- Build on correlated incidents, not raw alerts: Logic wired to enriched incidents fires once, on the actual condition, not on symptoms and duplicates.
- Apply graduated autonomy with safety gates: Give auto-remediation limited scope initially. Define guardrails that block action outside approved parameters, validate outcomes, and expand incrementally based on demonstrated accuracy.
- Keep full audit trails: Log every automated action with its reasoning, data inputs, and outcome so teams can review and tune over time.
- Define clear escalation paths: Every automated workflow needs a fallback: if the fix doesn’t work, the incident escalates immediately to the right team with full context attached.
- Measure and iterate: Track auto-remediation rate, false-positive action rate, and MTTR impact, then use that data to tune the system.
Frequently asked questions about auto-remediation
What is the difference between auto-remediation and self-healing IT?
In IT, self-healing is the broader vision: systems that detect, respond to, and recover from failures automatically. Auto-remediation is one of the mechanisms that makes it possible. Self-healing describes the outcome; auto-remediation describes how the system gets there.
Does auto-remediation work without a clean CMDB?
Yes. AI reasoning acts on enriched incident data and historical outcomes even when the CMDB is incomplete, and data quality improves as a byproduct of daily operations.
What types of incidents are best suited for auto-remediation?
High-volume, repeatable incident types with a low blast radius work best: service restarts, disk cleanup, alert suppression, and similar L1 patterns.
How does auto-remediation affect on-call engineers?
Auto-remediation reduces the volume of pages reaching on-call engineers by resolving L1 incidents before they need human attention. Engineers get paged for issues that require human judgment, not for noise.
What is autonomous incident resolution?
Autonomous incident resolution is the full incident lifecycle from detection through closure, handled by AI without human intervention for qualifying incident types. It’s the end state of mature auto-remediation and what Agentic ITOps makes operationally real.
PLATFORM
BigPanda Agentic ITOps
See how BigPanda uses agentic AI in IT operations.